


Lately, Giant Imaginative and prescient Language Fashions (LVLMs) comparable to LLava and MiniGPT-4 have demonstrated the flexibility to grasp photographs and obtain excessive accuracy and effectivity in a number of visible duties. Whereas LVLMs excel at recognizing frequent objects resulting from their intensive coaching datasets, they lack particular area information and have a restricted understanding of localized particulars inside photographs. This limits their effectiveness in Industrial Anomaly Detection (IAD) duties. Alternatively, current IAD frameworks can solely determine sources of anomalies and require guide threshold settings to differentiate between regular and anomalous samples, thereby proscribing their sensible implementation.
The first function of an IAD framework is to detect and localize anomalies in industrial situations and product photographs. Nevertheless, because of the unpredictability and rarity of real-world picture samples, fashions are usually skilled solely on regular information. They differentiate anomalous samples from regular ones primarily based on deviations from the standard samples. At the moment, IAD frameworks and fashions primarily present anomaly scores for take a look at samples. Furthermore, distinguishing between regular and anomalous situations for every class of things requires the guide specification of thresholds, rendering them unsuitable for real-world functions.
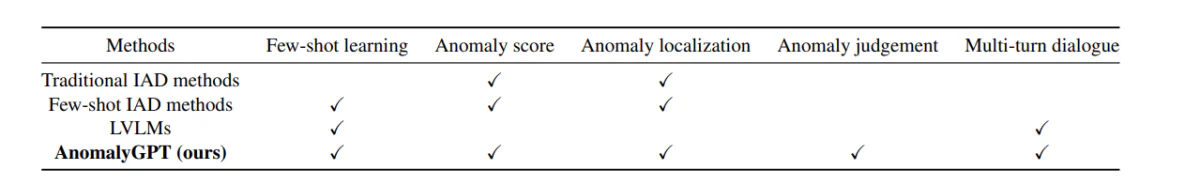
To discover the use and implementation of Giant Imaginative and prescient Language Fashions in addressing the challenges posed by IAD frameworks, AnomalyGPT, a novel IAD strategy primarily based on LVLM, was launched. AnomalyGPT can detect and localize anomalies with out the necessity for guide threshold settings. Moreover, AnomalyGPT also can supply pertinent details about the picture to interact interactively with customers, permitting them to ask follow-up questions primarily based on the anomaly or their particular wants.
Trade Anomaly Detection and Giant Imaginative and prescient Language Fashions
Current IAD frameworks may be categorized into two classes.
- Reconstruction-based IAD.
- Function Embedding-based IAD.
In a Reconstruction-based IAD framework, the first intention is to reconstruct anomaly samples to their respective regular counterpart samples, and detect anomalies by reconstruction error calculation. SCADN, RIAD, AnoDDPM, and InTra make use of the totally different reconstruction frameworks starting from Generative Adversarial Networks (GAN) and autoencoders, to diffusion mannequin & transformers.
Alternatively, in a Function Embedding-based IAD framework, the first motive is to give attention to modeling the function embedding of regular information. Strategies like PatchSSVD tries to discover a hypersphere that may encapsulate regular samples tightly, whereas frameworks like PyramidFlow and Cfl venture regular samples onto a Gaussian distribution utilizing normalizing flows. CFA and PatchCore frameworks have established a reminiscence financial institution of regular samples from patch embeddings, and use the space between the take a look at pattern embedding regular embedding to detect anomalies.
Each these strategies observe the “one class one mannequin”, a studying paradigm that requires a considerable amount of regular samples to study the distributions of every object class. The requirement for a considerable amount of regular samples make it impractical for novel object classes, and with restricted functions in dynamic product environments. Alternatively, the AnomalyGPT framework makes use of an in-context studying paradigm for object classes, permitting it to allow interference solely with a handful of regular samples.
Transferring forward, we’ve got Giant Imaginative and prescient Language Fashions or LVLMs. LLMs or Giant Language Fashions have loved great success within the NLP trade, and they’re now being explored for his or her functions in visible duties. The BLIP-2 framework leverages Q-former to enter visible options from Imaginative and prescient Transformer into the Flan-T5 mannequin. Moreover, the MiniGPT framework connects the picture phase of the BLIP-2 framework and the Vicuna mannequin with a linear layer, and performs a two-stage finetuning course of utilizing image-text information. These approaches point out that LLM frameworks might need some functions for visible duties. Nevertheless, these fashions have been skilled on common information, and so they lack the required domain-specific experience for widespread functions.
How Does AnomalyGPT Work?
AnomalyGPT at its core is a novel conversational IAD giant imaginative and prescient language mannequin designed primarily for detecting industrial anomalies and pinpointing their actual location utilizing photographs. The AnomalyGPT framework makes use of a LLM and a pre-trained picture encoder to align photographs with their corresponding textual descriptions utilizing stimulated anomaly information. The mannequin introduces a decoder module, and a immediate learner module to reinforce the efficiency of the IAD methods, and obtain pixel-level localization output.
Mannequin Structure
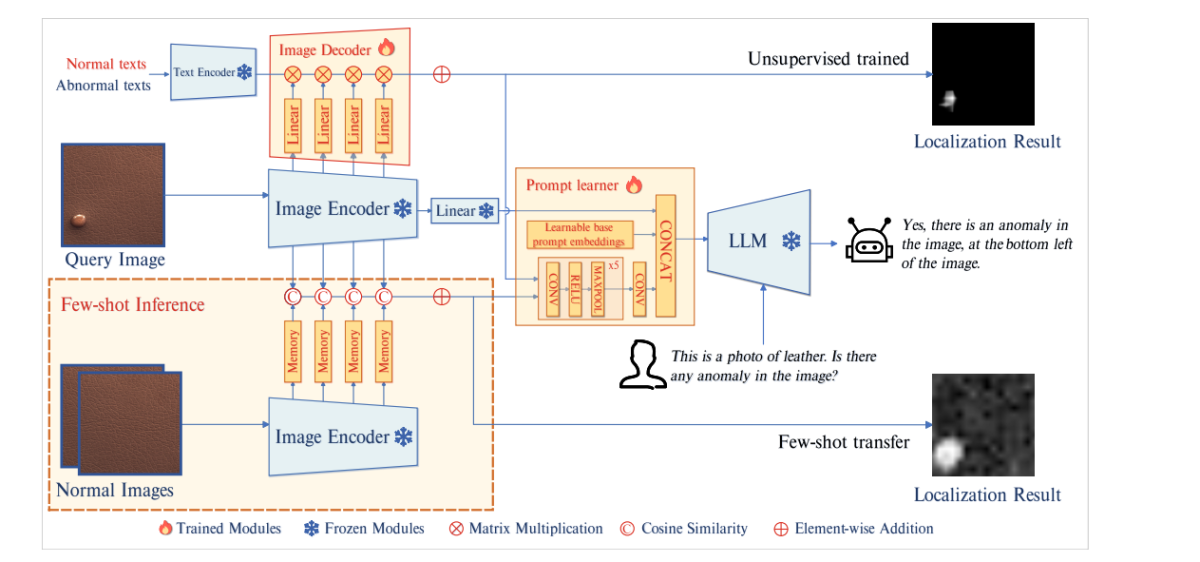
The above picture depicts the structure of AnomalyGPT. The mannequin first passes the question picture to the frozen picture encoder. The mannequin then extracts patch-level options from the intermediate layers, and feeds these options to a picture decoder to compute their similarity with irregular and regular texts to acquire the outcomes for localization. The immediate learner then converts them into immediate embeddings which can be appropriate for use as inputs into the LLM alongside the consumer textual content inputs. The LLM mannequin then leverages the immediate embeddings, picture inputs, and user-provided textual inputs to detect anomalies, and pinpoint their location, and create end-responses for the consumer.
Decoder
To attain pixel-level anomaly localization, the AnomalyGPT mannequin deploys a light-weight function matching primarily based picture decoder that helps each few-shot IAD frameworks, and unsupervised IAD frameworks. The design of the decoder utilized in AnomalyGPT is impressed by WinCLIP, PatchCore, and APRIL-GAN frameworks. The mannequin partitions the picture encoder into 4 levels, and extracts the intermediate patch stage options by each stage.
Nevertheless, these intermediate options haven’t been by the ultimate image-text alignment which is why they can’t be in contrast straight with options. To deal with this difficulty, the AnomalyGPT mannequin introduces extra layers to venture intermediate options, and align them with textual content options that symbolize regular and irregular semantics.
Immediate Learner
The AnomalyGPT framework introduces a immediate learner that makes an attempt to remodel the localization consequence into immediate embeddings to leverage fine-grained semantics from photographs, and likewise maintains the semantic consistency between the decoder & LLM outputs. Moreover, the mannequin incorporates learnable immediate embeddings, unrelated to decoder outputs, into the immediate learner to offer extra info for the IAD job. Lastly, the mannequin feeds the embeddings and authentic picture info to the LLM.
The immediate learner consists of learnable base immediate embeddings, and a convolutional neural community. The community converts the localization consequence into immediate embeddings, and varieties a set of immediate embeddings which can be then mixed with the picture embeddings into the LLM.
Anomaly Simulation
The AnomalyGPT mannequin adopts the NSA methodology to simulate anomalous information. The NSA methodology makes use of the Lower-paste approach by utilizing the Poisson picture modifying methodology to alleviate the discontinuity launched by pasting picture segments. Lower-paste is a generally used approach in IAD frameworks to generate simulated anomaly photographs.
The Lower-paste methodology includes cropping a block area from a picture randomly, and pasting it right into a random location in one other picture, thus making a portion of simulated anomaly. These simulated anomaly samples can improve the efficiency of IAD fashions, however there’s a disadvantage, as they will usually produce noticeable discontinuities. The Poisson modifying methodology goals to seamlessly clone an object from one picture to a different by fixing the Poisson partial differential equations.
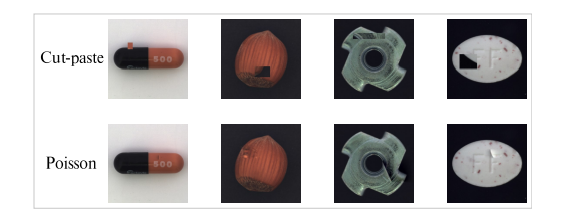
The above picture illustrates the comparability between Poisson and Lower-paste picture modifying. As it may be seen, there are seen discontinuities within the cut-paste methodology, whereas the outcomes from Poisson modifying appear extra pure.
Query and Reply Content material
To conduct immediate tuning on the Giant Imaginative and prescient Language Mannequin, the AnomalyGPT mannequin generates a corresponding textual question on the idea of the anomaly picture. Every question consists of two main parts. The primary a part of the question consists of an outline of the enter picture that gives details about the objects current within the picture together with their anticipated attributes. The second a part of the question is to detect the presence of anomalies throughout the object, or checking if there’s an anomaly within the picture.
The LVLM first responds to the question of if there’s an anomaly within the picture? If the mannequin detects anomalies, it continues to specify the situation and the variety of the anomalous areas. The mannequin divides the picture right into a 3×3 grid of distinct areas to permit the LVLM to verbally point out the place of the anomalies as proven within the determine under.

The LVLM mannequin is fed the descriptive information of the enter with foundational information of the enter picture that aids the mannequin’s comprehension of picture parts higher.
Datasets and Analysis Metrics
The mannequin conducts its experiments totally on the VisA and MVTec-AD datasets. The MVTech-AD dataset consists of 3629 photographs for coaching functions, and 1725 photographs for testing which can be cut up throughout 15 totally different classes which is why it is among the hottest dataset for IAD frameworks. The coaching picture options regular photographs solely whereas the testing photographs function each regular and anomalous photographs. Alternatively, the VisA dataset consists of 9621 regular photographs, and practically 1200 anomalous photographs which can be cut up throughout 12 totally different classes.
Transferring alongside, similar to the present IAD framework, the AnomalyGPT mannequin employs the AUC or Space Below the Receiver Working Traits as its analysis metric, with pixel-level and image-level AUC used to evaluate anomaly localization efficiency, and anomaly detection respectively. Nevertheless, the mannequin additionally makes use of image-level accuracy to guage the efficiency of its proposed strategy as a result of it uniquely permits to find out the presence of anomalies with out the requirement of establishing the thresholds manually.
Outcomes
Quantitative Outcomes
Few-Shot Industrial Anomaly Detection
The AnomalyGPT mannequin compares its outcomes with prior few-shot IAD frameworks together with PaDiM, SPADE, WinCLIP, and PatchCore because the baselines.

The above determine compares the outcomes of the AnomalyGPT mannequin compared with few-shot IAD frameworks. Throughout each datasets, the strategy adopted by AnomalyGPT outperforms the approaches adopted by earlier fashions when it comes to image-level AUC, and likewise returns good accuracy.
Unsupervised Industrial Anomaly Detection
In an unsupervised coaching setting with a lot of regular samples, AnomalyGPT trains a single mannequin on samples obtained from all courses inside a dataset. The builders of AnomalyGPT have opted for the UniAD framework as a result of it’s skilled beneath the identical setup, and can act as a baseline for comparability. Moreover, the mannequin additionally compares towards JNLD and PaDim frameworks utilizing the identical unified setting.

The above determine compares the efficiency of AnomalyGPT when in comparison with different frameworks.
Qualitative Outcomes

The above picture illustrates the efficiency of the AnomalyGPT mannequin in unsupervised anomaly detection methodology whereas the determine under demonstrates the efficiency of the mannequin within the 1-shot in-context studying.

The AnomalyGPT mannequin is able to indicating the presence of anomalies, marking their location, and offering pixel-level localization outcomes. When the mannequin is in 1-shot in-context studying methodology, the localization efficiency of the mannequin is barely decrease when in comparison with unsupervised studying methodology due to absence of coaching.
Conclusion
AnomalyGPT is a novel conversational IAD-vision language mannequin designed to leverage the highly effective capabilities of huge imaginative and prescient language fashions. It cannot solely determine anomalies in a picture but additionally pinpoint their actual areas. Moreover, AnomalyGPT facilitates multi-turn dialogues targeted on anomaly detection and showcases excellent efficiency in few-shot in-context studying. AnomalyGPT delves into the potential functions of LVLMs in anomaly detection, introducing new concepts and potentialities for the IAD trade.

